Datasets
- CVPR 2023: 5th Workshop and Competition on Affective Behavior Analysis in-the-wild (ABAW)
- ECCV 2022: 4th Workshop and Competition on Affective Behavior Analysis in-the-wild (ABAW)
- CVPR 2022: 3rd Workshop and Competition on Affective Behavior Analysis in-the-wild (ABAW)
- ICCV 2021: 2nd Workshop and Competition on Affective Behavior Analysis in-the-wild (ABAW)
- Synthesizing Coupled 3D Face Modalities by TBGAN
- Face Bio-metrics under COVID (Masked Face Recognition Challenge & Workshop ICCV 2021)
- First Affect-in-the-Wild Challenge
- FG-2020 Competition: Affective Behavior Analysis in-the-wild (ABAW)
- Aff-Wild2 database
- The CONFER Database
- In-The-Wild 3D Morphable Models: Code and Data
- Sound of Pixels
- Lightweight Face Recognition Challenge & Workshop (ICCV 2019)
- Audiovisual Database of Normal-Whispered-Silent Speech
- Deformable Models of Ears in-the-wild for Alignment and Recognition
- 300 Videos in the Wild (300-VW) Challenge & Workshop (ICCV 2015)
- 1st 3D Face Tracking in-the-wild Competition
- The Fabrics Dataset
- The Mobiface Dataset
- Large Scale Facial Model (LSFM)
- AgeDB
- AFEW-VA Database for Valence and Arousal Estimation In-The-Wild
- Special Issue on Behavior Analysis "in-the-wild"
- Body Pose Annotations Correction (CVPR 2016)
- KANFace
- MeDigital
- FG-2020 Workshop "Affect Recognition in-the-wild: Uni/Multi-Modal Analysis & VA-AU-Expression Challenges"
- 4DFAB: A Large Scale 4D Face Database for Expression Analysis and Biometric Applications
- First Faces in-the-wild Workshop-Challenge
- Affect "in-the-wild" Workshop
- 2nd Facial Landmark Localisation Competition - The Menpo BenchMark
- Facial Expression Recognition and Analysis Challenge 2015
- The SEWA Database
- Mimic Me
- 300 Faces In-The-Wild Challenge (300-W), IMAVIS 2014
- MAHNOB-HCI-Tagging database
- 300 Faces In-the-Wild Challenge (300-W), ICCV 2013
- MAHNOB Laughter database
- MAHNOB MHI-Mimicry database
- Facial point annotations
- MMI Facial expression database
- SEMAINE database
- iBugMask: Face Parsing in the Wild (ImaVis 2021)
- iBUG Eye Segmentation Dataset
Code
- Valence/Arousal Online Annotation Tool
- The Menpo Project
- The Dynamic Ordinal Classification (DOC) Toolbox
- Gauss-Newton Deformable Part Models for Face Alignment in-the-Wild (CVPR 2014)
- Robust and Efficient Parametric Face/Object Alignment (2011)
- Discriminative Response Map Fitting (DRMF 2013)
- End-to-End Lipreading
- DS-GPLVM (TIP 2015)
- Subspace Learning from Image Gradient Orientations (2011)
- Discriminant Incoherent Component Analysis (IEEE-TIP 2016)
- AOMs Generic Face Alignment (2012)
- Fitting AAMs in-the-Wild (ICCV 2013)
- Salient Point Detector (2006/2008)
- Facial point detector (2010/2013)
- Chehra Face Tracker (CVPR 2014)
- Empirical Analysis Of Cascade Deformable Models For Multi-View Face Detection (IMAVIS 2015)
- Continuous-time Prediction of Dimensional Behavior/Affect
- Real-time Face tracking with CUDA (MMSys 2014)
- Facial Point detector (2005/2007)
- Facial tracker (2011)
- Salient Point Detector (2010)
- AU detector (TAUD 2011)
- Action Unit Detector (2016)
- AU detector (LAUD 2010)
- Smile Detectors
- Head Nod Shake Detector (2010/2011)
- Gesture Detector (2011)
- Head Nod Shake Detector and 5 Dimensional Emotion Predictor (2010/2011)
- Gesture Detector (2010)
- HCI^2 Framework
- FROG Facial Tracking Component
- SEMAINE Visual Components (2008/2009)
- SEMAINE Visual Components (2009/2010)
First Affect-in-the-Wild Challenge
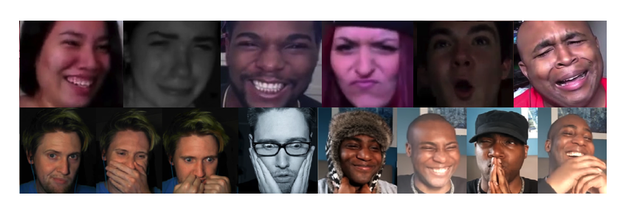
Frames from the Aff-Wild database which show subjects in different emotional states, of different ethnicities, in a variety of head poses, illumination conditions and occlusions.
Update
The Aff-Wild database has been extended with more videos and annotations in terms of action units, basic expressions (and valence-arousal). The newly formed database is called Aff-Wild2. More details can be found here.
How to acquire the data
For more details about the database and the procedure for requesting access to it, please visit this website.
Additional Info
These data are in accordance with the paper Deep Affect Prediction in-the-wild: Aff-Wild Database and Challenge, Deep Architectures, and Beyond.
In this paper, we introduce the AffWild benchmark, we report on the results of the First Affect-in-the-wild Challenge, we design state-of-the-art Deep Neural Architectures -including the AffWildNet (best performing Network on Aff-Wild)- and exploit the AffWild database for learning features, which can be used as priors for achieving best performances for dimensional and categorical emotion recognition.
Evaluation of your predictions on the test set
If you want to evaluate your models on the Aff-Wild's test set, send an email with your predictions to: d.kollias@qmul.ac.uk
As far as the format is concerned, send the files with names as the corresponding videos. Each line of each file should contain the values of valence and arousal for the corresponding frame separated by comma ,i.e. for file 271.csv:
line 1 should be: valence_of_first_frame,arousal_of_first_frame
line 2 should be: valence_of_second_frame,arousal_of_second_frame
...
last line: valence_of_last_frame,arousal_of_last_frame
Note that in your files you should include predictions for all frames in the video (irregardless if the bounding box failed or not).
News of the Challenge
- The Aff-Wild Challenge training sets are released.
- The test data are out. You have 8 days to submit your results if you want to be part of the challenge (until 30th of March).
- We are providing the bounding boxes and the landmarks for the face in the video by using an automatic method.
Aff-Wild DATA
The Affect-in-the-Wild Challenge to be held in conjunction with International Conference on Computer Vision & Pattern Recognition (CVPR) 2017, Hawaii, USA.
Organisers
Chairs:
Stefanos Zafeiriou, Imperial College London, UK s.zafeiriou@imperial.ac.uk
Mihalis Nicolaou, Goldsmiths University of London, UK m.nicolaou@gold.ac.uk
Irene Kotsia, Hellenic Open University, Greeece, drkotsia@gmail.com
Fabian Benitez-Quiroz, Ohio State University, USA benitez-quiroz.1@osu.edu
Guoying Zhao, University of Oulu, gyzhao@ee.oulu.fi
Data Chairs:
Dimitris Kollias, Imperial College London, UK dimitrios.kollias15@imperial.ac.uk
Athanasios Papaioannou, Imperial College London, UK a.papaioannou11@imperial.ac.uk
Scope
The human Face is arguably the most studied object in computer vision. Recently, tens of databases have been collected under unconstrained conditions (also referred to as “in-thewild”) for many face related task such as face detection, face verification and facial landmark localisation. However, well-established databases and benchmarks “in-the-wild” do not exist, specifically for problems such as estimation of affect in a continuous dimensional space (e.g., valence and arousal) in videos displaying spontaneous facial behaviour. In CVPR 2017, we propose to make a significant step further and propose new comprehensive benchmarks for assessing the performance of facial affect/behaviour analysis/understanding “in-the-wild”. To the best of our knowledge, this is the first time that an attempt for benchmarking the efforts of valence and arousal "in-the-wild".
The Aff-Wild Challenge
For analysis of continuous emotion dimensions (such as valence and arousal) we propose to advance previous works by providing around 300 videos (over 15 hours of data) annotated with regards to valence and arousal all captured “in-the-wild” (the main source being Youtube videos). 252 videos will be provided for training and the remaining ones (46) for testing.
Even though the majority of the videos are under the creative commons licence (https://support.google.com/youtube/answer/2797468?hl=en-GB), the subjects have been notified about the use of their videos in our study.
Training
The training data contain the videos and their corresponding annotation (#_arousal.txt and #_valence.txt, # is the number of video). Furthermore, to facilitate training, especially for people that do not have access to face detectors/tracking algorithms, we provide bounding boxes and landmarks for the face(s) in the videos.
- The dataset and annotations are available for non-commercial research purposes only.
- All the training/testing images of the dataset are obtained from Youtube. We are not responsible for the content nor the meaning of these images.
- You agree not to reproduce, duplicate, copy, sell, trade, resell or exploit for any commercial purposes, any portion of the images and any portion of derived data.
- You agree not to further copy, publish or distribute any portion of annotations of the dataset. Except, for internal use at a single site within the same organization it is allowed to make copies of the dataset.
- We reserve the right to terminate your access to the dataset at any time.
- If your face is displayed in any video and you want it to be removed you can email us at any time.
Testing
Participants will have their algorithms tested on other videos which will be provided in a predefined date (see below). This dataset aims at testing the ability of current systems for estimating valence and arousal in unseen subjects. To facilitate testing we provide bounding boxes and landmarks for the face(s) present in the testing videos.
Performance Assessment
Performance will be assessed using the standard concordance correlation coefficient (CCC), as well as the mean squared error objective.
Faces in-the-wild 2017 Workshop
Our aim is to accept up to 10 papers to be orally presented at the workshop.
Submission Information:
Challenge participants should submit a paper to the Faces-in-the-wild Workshop, which summarises the methodology and the achieved performance of their algorithm. Submissions should adhere to the main CVPR 2017 proceedings style. The workshop papers will be published in the CVPR 2017 proceedings. Please sign up in the submissions system to submit your paper.
Important Dates:
- 27 January: Announcement of the Challenges
- 30 January: Release of the training videos
- 22 March: Release of the test data
- 31 March: Deadline of returning results (Midnight GMT)
- 3 April: Return of the results to authors
- 20 April: Deadline for paper submission
- 27 April: Decisions
- 19 May: Camera-ready deadline
- 26 July: Workshop date
Contact:
Workshop Administrator: dimitrios.kollias15@imperial.ac.uk
References
[1] Stefanos Zafeiriou, Athanasios Papaioannou, Irene Kotsia, Mihalis Nicolaou, Guoying Zhao, Facial Affect in-the-wild: A survey and a new database, International Conference on Computer Vision and Pattern Recognition (CVPR) Workshops, Affect "in-the-wild" Workshop, 2016.
Program Committee:
- Jorge Batista, University of Coimbra (Portugal)
- Richard Bowden, University of Surrey (UK)
- Jeff Cohn, CMU/University of Pittsburgh (USA)
- Roland Goecke, University of Canberra (AU)
- Peter Corcoran, NUI Galway (Ireland)
- Fred Nicolls, University of Cape Town (South Africa)
- Mircea C. Ionita, Daon (Ireland)
- Ioannis Kakadiaris, University of Houston (USA)
- Stan Z. Li, Institute of Automation Chinese Academy of Sciences (China)
- Simon Lucey, CMU (USA)
- Iain Matthews, Disney Research (USA)
- Aleix Martinez, University of Ohio (USA)
- Dimitris Metaxas, Rutgers University (USA)
- Stephen Milborrow, sonic.net
- Louis P. Morency, University of South California (USA)
- Ioannis Patras, Queen Mary University (UK)
- Matti Pietikainen, University of Oulu (Finland)
- Deva Ramaman, University of Irvine (USA)
- Jason Saragih, Commonwealth Sc. & Industrial Research Organisation (AU)
- Nicu Sebe, University of Trento (Italy)
- Jian Sun, Microsoft Research Asia
- Xiaoou Tang, Chinese University of Hong Kong (China)
- Fernando De La Torre, Carnegie Mellon University (USA)
- Philip A. Tresadern, University of Manchester (UK)
- Michel Valstar, University of Nottingham (UK)
- Xiaogang Wang, Chinese University of Hong Kong (China)
- Fang Wen, Microsoft Research Asia
- Lijun Yin, Binghamton University (USA)
Sponsors:
This challenge has been supported by a distinguished fellowship to Dr. Stefanos Zafeiriou by TEKES.